See the real drivers
Break down input, cache, output, model, effort, provider, session, and subagent usage.
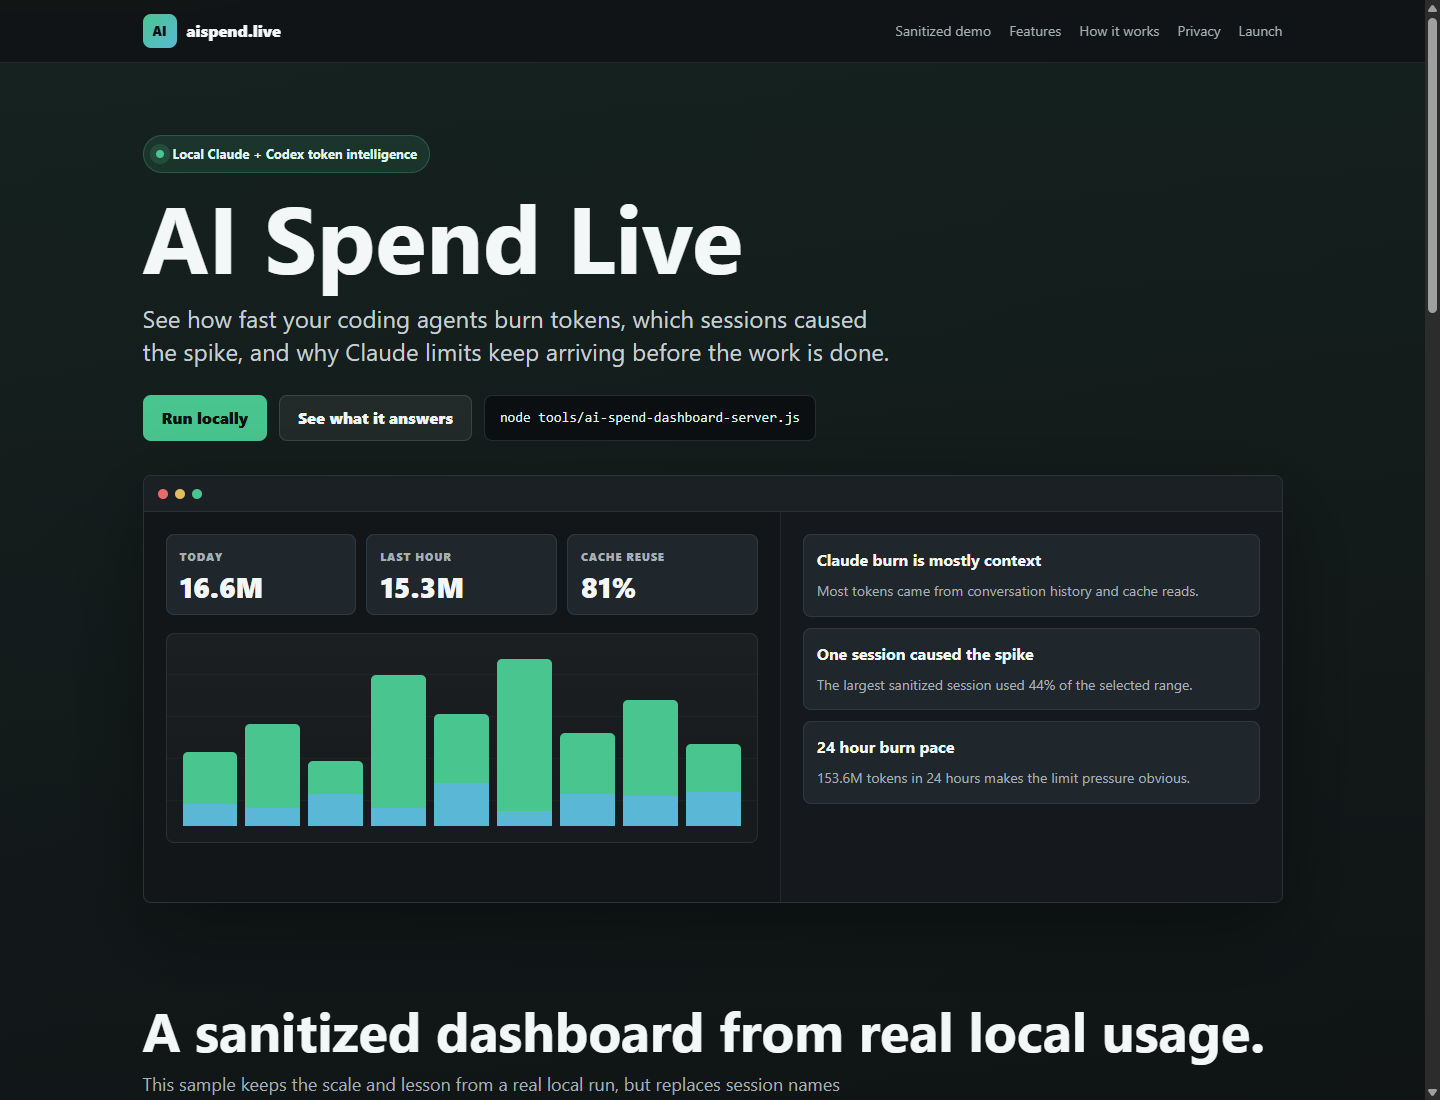
Turn local Claude Code and Codex history into useful answers: which session spiked, which model drove it, what subagents multiplied the context, and when to split, summarize, or step down.
No account. No telemetry. No prompt text in the dashboard payload.
Costs are API-equivalent estimates. Subscription plans use published message windows and fair-use limits, so AI Spend keeps plan pressure, API dollars, and OpenAI credits separate.
Break down input, cache, output, model, effort, provider, session, and subagent usage.
Includes GPT-6 Astra, GPT-6.1 Sol and Terra, GPT-6 Luna, and Claude Fable, Opus, Sonnet, and Haiku tiers.
Spot context-heavy threads, fan-out, burst pressure, cache reuse, and the turns worth restarting.
Node.js 22+ is recommended. The dashboard binds to localhost by default.
npm install
npm test
npm run dashboard

# open http://127.0.0.1:9020/